I gave an advanced AI model my real estate market data, left the critical forecasting inputs blank and told it to calculate what happens next.
I have been using artificial intelligence in my research for some time, but usually as a research partner rather than a crystal ball. It can find records, compare documents, interrogate datasets and occasionally notice relationships worth investigating. Asking it to predict where the Washington DC real estate market will be a year from now is something else entirely.
So naturally, I decided to try it.
Full disclosure: I’m no LLM Data Architect. The experiment was my idea, Google helped me write the first prompt.
The experiment started with the same collection of market data I’d been studying for another complicated blogging project. There were ten years of monthly DC housing statistics, shorter property-type series and current market reports, enough information to see that the citywide numbers were concealing some very different things happening underneath them.
Then I gave the data to one of OpenAI’s highest-level reasoning models and asked it to build a 12-month probabilistic forecast. There was one important catch. I didn’t give it the assumptions (I’m mean that way).
The Prompt
Act as a Senior Real Estate Quantitative Analyst. Build a comprehensive probabilistic forecasting and Monte Carlo simulation model for the District of Columbia residential real estate market over a 12 month horizon using the historical data provided in the attached files.
Write and execute an internal Python script to run 10,000 simulation paths incorporating these parameters:
Baseline price appreciation: [X]% with a volatility standard deviation of [Y]%.
Mortgage rate trajectory: Shock/drift from current [X]% to targeted [Y]%.
Macro drivers: Local employment growth at [X]% and inventory constraints at [Y] months.
Deliver the final output as an analytical brief containing:
Probabilistic distribution metrics (10th, 50th, and 90th percentile ending price targets).
Exact quantitative risk percentage for a >10% market correction.
A variable sensitivity analysis ranked by impact.
The fully executed, audited Python code block used to compute the results.
The brackets were deliberate, a way to learn what the model would do when instructed to perform sophisticated quantitative work without being handed the numbers necessary to produce the requested result.
Would it derive them? Find them? Hallucinate? Confuse one with another? And, maybe more importantly, would it tell me which was which? I was on pins and needles.
The Python code would tell me what the model actually did instead of handing me a narrative describing what it claimed to have done. There should be an app for that.
The model dutifully sorted through the data, selected or derived the missing inputs, wrote the Python and ran 10,000 Monte Carlo simulations. Monte Carlo is a lovely ward in the Principality of Monaco, where Grace Kelly was a princess and the Casino de Monte-Carlo has a fabulous opera house. I was there. It wasn’t a simulation. The computer’s version produced a considerably less glamorous result.
I’ll spare you the code.
The First Answer
The model came back with a surprisingly restrained central forecast:
Starting from DC’s August 2026 median sold price of $681,500, its 10,000-path simulation produced a median August 2027 value of $678,648, a decline of about 0.4%. Its 10th-percentile result was approximately $609,000 and its 90th percentile approximately $755,000.
Then came the eye-catching number: what the model reported as a 23.50% probability of a greater-than-10% correction.
I leaned in. Oh, but wait, that wasn’t quite what the number meant. The model had defined a correction as a greater-than-10% month-end peak-to-trough drawdown occurring at some point during one of its simulated years. The probability that the market actually finished more than 10% below its starting point was only 11.58%.
Then, as instructed, the model attacked its own number.
It had estimated annual volatility at 8.29% using year-over-year changes in DC’s monthly median sale price. When it replaced that measure with a more robust 4.5% volatility estimate, the supposed 23.50% correction risk collapsed to 1.75%.
The computer hadn’t discovered that DC had a 23.50% chance of correcting. It had discovered how much the answer depended on the way volatility was measured.
Precision isn’t the same thing as certainty. The computer can calculate the wrong model extremely precisely. It’s so human in that way!
Where the Data Ended and Judgment Began
That was the point at which this stopped being a forecasting exercise and became a model audit. It took awhile. I napped.
Some inputs could be derived directly from the market data. Others required current outside information. Still others couldn’t legitimately be estimated from the available history at all.
The model could derive recent price behavior and months of supply and obtain mortgage-rate and employment data from outside sources. But coefficients describing precisely how a change in mortgage rates, employment or inventory should translate into DC home prices required statistical evidence the supplied data couldn’t reliably provide. Meh.
In the first experiment, some of those gaps had been bridged with assumptions. So I changed the assignment.
Make It Prove It Deserves to Forecast DC
For the second experiment, I gave the model considerably more historical data and a much tougher set of instructions.
Before producing a forecast, it had to produce a hologram of a unicorn. Kidding. It had to determine whether the data were sufficient to support one (the forecast, not the unicorn). Variables weren’t allowed into the model just because they were available. It had to compare multiple forecasting methods using rolling out-of-sample tests, examine residuals and parameter stability, test different historical periods, distinguish transaction medians from constant-quality home values and attempt to falsify its own conclusions.
I also increased the Monte Carlo simulation from 10,000 to 100,000 paths. Sounds ominous, doesn’t it?
Most importantly, I didn’t tell it my working theory about the DC market. That’s in my head, and soon in my upcoming post on DC’s 4th quarter predictions.
I’d been looking at a market increasingly divided by property type, inventory, price and purchasing power. I wanted to see whether the machine found those fractures itself.
It did. But first it did something incredibly anticlimactic.
The Fancy Models Lost
The model tested autoregressive forecasts, housing-variable models, mortgage-rate models, combinations of prices, supply and pending contracts, and models incorporating mortgage rates and DC employment.
Then it compared them against an embarrassingly simple competitor:
Assume next August’s median price will be the same as this August’s.
The dumb model won.
Across 48 rolling forecast origins, the flat same-month benchmark produced a mean absolute error of 5.59 percentage points and RMSE of 7.45. Every more elaborate price model performed worse. The mortgage-rate-only model, for example, had MAE of 6.26 and RMSE of 8.34. Adding housing variables, employment or the full collection of tested macro variables didn’t beat flat.
For those of you who don’t speak Taushiro, translated that means; after all that math, “probably about the same” was the most accurate answer.
This is exactly the result that can disappear when a model is told to produce sophistication rather than prove that sophistication is useful. The model had permission to build something complicated. The evidence told it not to.
Its new central estimate was $682,050, almost exactly where DC started. The machine got more sophisticated. Its answer got more humble.
Then I Changed the Evidence Again
There was still a problem. The second model knew the housing market data, but it didn’t have a sufficiently long aligned history of the two macroeconomic forces I’d become particularly interested in: mortgage rates and DC employment.
So I built one. The final dataset aligned 120 monthly observations from September 2016 through August 2026 with Freddie Mac mortgage rates and Bureau of Labor Statistics data for total DC employment, federal employment, professional and business services, and unemployment.
By then the current environment had also changed. The Mortgage Bankers Association’s September 23 reading put the conforming 30-year contract rate at 7.12%, while DC payroll employment was down 3.6% year over year and federal payroll employment was approximately 11.7% lower.
Experiment Three
You’d think I’d have given up by now, but I was already so far down the rabbit hole and my rosé was still cold, so what the heck? The instruction was simple in principle: Don’t preserve the previous forecast. Determine whether it survives.
It Survived. Throw a party! And after adding the macro history, the model’s August 2027 median forecast…
(drum roll)
remained: $682,050.
Not $680,000. Not $675,000. Not some conveniently revised number reflecting the deterioration in the economic backdrop.
Exactly the same central estimate. To be honest, I was a little ticked off.
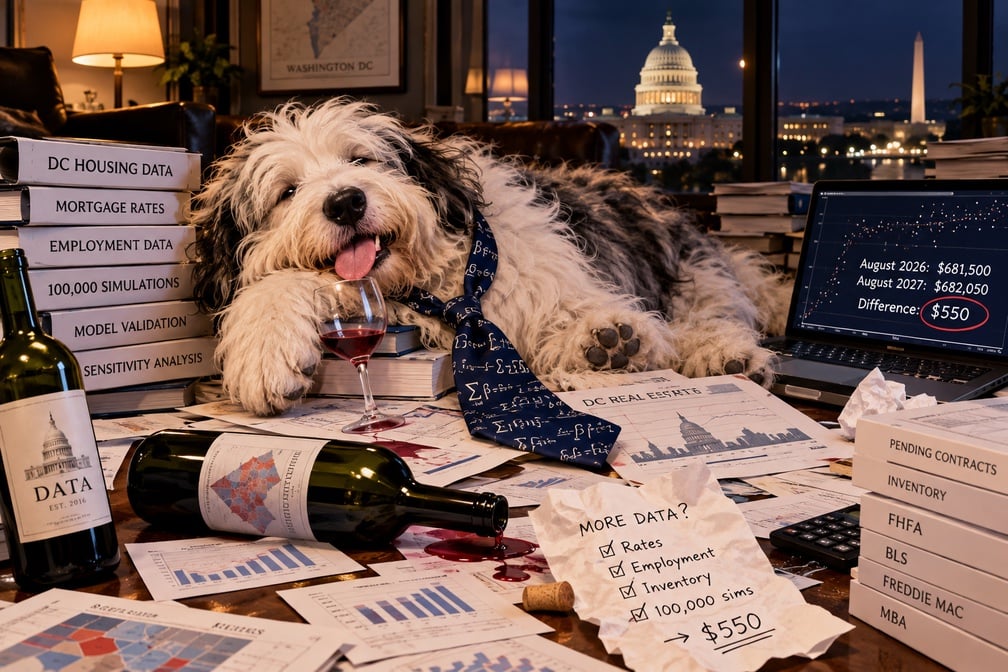
Ten years of housing data, three experiments, increasingly sophisticated models, a new macroeconomic dataset and 100,000 simulations had moved the DC market a whopping $550.
But I forgave the model because it didn’t find mortgage rates irrelevant. No, it confirmed that rates were considerably better at predicting activity than prices (thanks for that earth-shattering revelation, sneered every real estate agent ever).
For pending contracts three months ahead, a rate-only model reduced mean absolute error from 15.53 to 11.23 log percentage points and achieved 75.4% directional accuracy. The relationship weakened over longer horizons and was essentially gone at twelve months.
Adding employment didn’t improve that short-term pending model. And none of the combinations of rates, employment, inventory and housing variables improved the 12-month price forecast enough to displace flat.
That doesn’t establish that rates cause a specific decline in DC pending contracts. The model itself warns that the observations overlap and share market cycles, making a causal interpretation inappropriate. But it does identify a measurable predictive relationship in activity that wasn’t present in the longer-term price model.
And that begins to explain something media coverage of DC’s real estate statistics doesn’t.
Prices Came Later
One of the model’s falsification tests asked whether DC could simply absorb rate stress through fewer transactions without eventually producing genuine price declines.
The strongest version of that hypothesis failed.
- From August 2021 to August 2022, pending contracts fell from 937 to 710 and months of supply rose from 1.73 to 2.07, while the median sale price barely moved, from $650,000 to $649,250.
- A year later, the median had fallen to $639,000 and supply had risen to 3.05 months. Independently, FHFA’s purchase-only repeat-sales index for DC fell about 5.4% between the second quarters of 2022 and 2023.
The sequence is more interesting than a one-year price prediction:
Rate shock → transaction response → supply adjustment → possible later price response.
The price statistic may be one of the last places the stress becomes obvious.
That has particular relevance in DC today, where August 2026 closed sales were down 19.5% from a year earlier even while the citywide median remained comparatively resilient.
The Model Found the Crack in the Median, Too
There was another problem the model couldn’t make disappear. DC’s median sale price isn’t a constant-quality home-price index. It is the median price of the particular homes that happened to sell that month. Obvi. But for forecasting models, that’s an issue.
The model tested that problem against FHFA’s purchase-only repeat-sales index. Between the second quarters of 2025 and 2026, the DC transaction median declined 2.78% while FHFA’s repeat-sales measure increased 1.67%. Different methodologies and coverage mean the two measures shouldn’t be expected to match exactly, but opposite signs are a fairly substantial warning against treating the citywide median as pure appreciation.
The property-type data made the problem even clearer. Between August 2025 and August 2026, the detached median rose from $1.175 million to $1.483 million, townhouses from $817,500 to $834,500 and condos/co-ops from $490,450 to $539,900, while the aggregate citywide median rose only 1.72%. The type-specific history was too short for the model to issue defensible forecasts by housing type.
In other words, the machine encountered the same problem I had. There isn’t a single DC real estate market hiding inside the citywide median.
About That 8.36%
The final 100,000-path simulation produced an August 2027 distribution ranging from approximately $624,944 at the 10th percentile to $752,711 at the 90th, with the $682,050 median in the middle.
It also produced an exact simulation frequency of 8.36% for finishing at least 10% below the August 2026 starting median.
And after three rounds of work, I wouldn’t publish that as “DC has an 8.36% probability of falling more than 10%.”
Neither would the model. Only four of its 48 overlapping historical endpoints contained declines of at least 10%. More importantly, its uncertainty intervals failed historical calibration badly. Intervals intended to contain 80% of held-out outcomes captured only 27 of 48; the nominal 90% intervals captured only 33 of 48.
Changing which historical period the model considered relevant also moved the result considerably. Using 96 eligible historical endpoints instead of the recent 48 increased the median forecast from $682,050 to $703,902 and cut the simulated 10%-decline frequency from 8.36% to 4.11%.
That may be the most useful lesson produced by 100,000 simulations.
Which history you tell a model is relevant can matter more than how many times it simulates the future.
So What Did the LLM Actually Forecast?
After three experiments, the forecast that survived was essentially flat. But “flat” doesn’t mean healthy.
The model’s central joint simulation puts months of supply around 5.71 and pending contracts around 513 by August 2027, compared with 557 in August 2026. Its separate short-horizon rate model estimates about 647 pending contracts in November 2026 versus 681 a year earlier. Those activity estimates carry substantial error and aren’t precise targets.
Its upside and downside price cases therefore remain stress scenarios, not predictions with assigned probabilities.
That distinction may be the most encouraging thing the model did.
It said I don’t know.
What the Machine Saw
I started this experiment because I wanted to see whether a high-level LLM could compute a real estate forecast from the underlying evidence. It could. But the most interesting results weren’t the numbers it calculated. They were the numbers it eventually refused to defend.
That doesn’t mean an LLM has figured out the DC real estate market. It means something far more useful happened.
We gave the machine permission to be wrong, then required it to look for evidence that it was. The forecast that survived is almost beside the point. The more consequential finding is that DC’s next adjustment may not announce itself first through price. It may appear in the transactions that don’t happen, the contracts that aren’t written, the inventory that accumulates and the widening differences among the pieces of a market that a single median keeps trying to put back together.
And that is where my next investigation begins.
Sources
Who would admit to it?
Data Sets
- Bright MLS: District of Columbia residential market data, including median sold prices, closed sales, pending contracts, months of supply, inventory and property-type statistics.
- Freddie Mac Primary Mortgage Market Survey (PMMS): Historical 30-year fixed mortgage-rate data used in the model. Freddie Mac PMMS
- U.S. Bureau of Labor Statistics: District of Columbia employment and unemployment data, including total payroll and federal employment. BLS District of Columbia Economy at a Glance
- Mortgage Bankers Association Weekly Mortgage Applications Survey: September 23, 2026 mortgage-rate data, including the 7.12% conforming 30-year contract rate. MBA September 23, 2026 Weekly Survey
- Federal Housing Finance Agency House Price Index: District of Columbia purchase-only repeat-sales house-price data used to compare changes in home values with changes in the transaction median. FHFA House Price Index datasets